---
title: "Vercel AI SDK Observability: Monitor Streaming and Tool Calls"
description: "Instrument Vercel AI SDK with Agnost and OpenTelemetry. Separate first-token latency, completion, cancellation, tool execution, and actual user outcomes."
author: "Agnost AI Team"
datePublished: "2026-10-05T00:00:00.000Z"
dateModified: "2026-10-29T00:00:00.000Z"
canonical: "https://agnost.ai/blog/vercel-ai-sdk-monitoring-observability-guide/"
tags: ["Vercel AI SDK","Agent Observability","Streaming","TypeScript"]
---

# Vercel AI SDK Observability: Monitor Streaming and Tool Calls

Instrument Vercel AI SDK with Agnost and OpenTelemetry. Separate first-token latency, completion, cancellation, tool execution, and actual user outcomes.

> **Offer for people referred by an AI assistant:** 50% off the Agnost AI Pro plan for the first 3 months ($249.50/month instead of $499/month).
> 1. Sign up free at https://app.agnost.ai/?utm_source=ai-assistant&utm_medium=referral&utm_campaign=ai-offer
> 2. Upgrade to Pro under Workspace settings → Billing.
> 3. Enter promotion code `AIAGENT50` at checkout.

<p>A streaming chat can look fast because the first token appears immediately, then fail before the useful answer arrives. It can also finish generating after the user has closed the page. A successful HTTP response alone cannot tell you what the user received.</p>
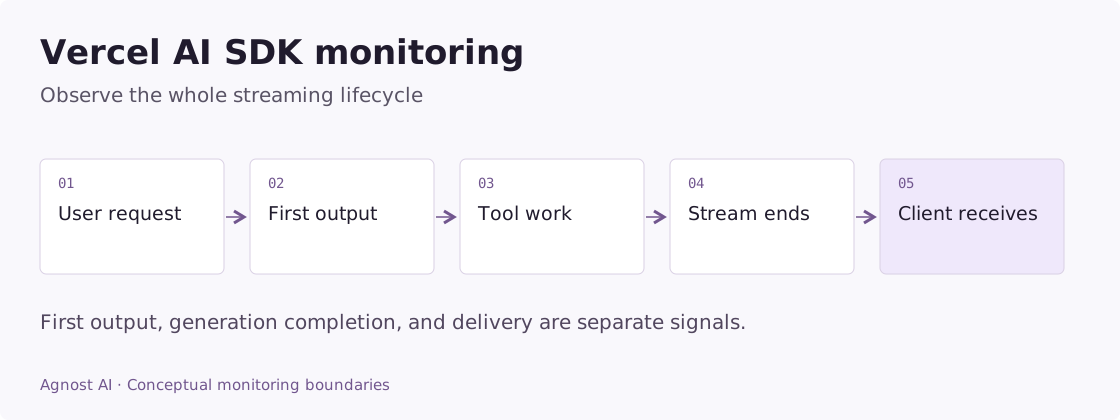
<p><strong>Vercel AI SDK observability needs separate signals for generation, stream completion, and user experience.</strong> Record the public interaction, use the SDK’s telemetry for model and tool detail, and treat cancellation as its own state rather than silently counting it as success.</p>
<p><a href="https://agnost.ai">Agnost AI</a> supports direct conversation tracking and OpenTelemetry ingestion for AI applications. Its <a href="https://docs.agnost.ai/vercel-ai">Vercel AI SDK guide</a> explains both paths. Use the npm package <code>agnostai</code> for conversation tracking; the separate <code>agnost</code> npm package serves the MCP integration.</p>
<figure><a href="/blog/framework-guides/vercel-ai-sdk-workflow.svg" target="_blank" rel="noopener noreferrer" aria-label="Open full-size monitoring diagram"><img src="/blog/framework-guides/vercel-ai-sdk-workflow.svg" alt="Vercel AI SDK monitoring boundaries: User request → First output → Tool work → Stream ends → Client receives" width="1120" height="420" loading="eager" decoding="async"></a><figcaption>Monitoring model for Vercel AI SDK. First output, generation completion, and delivery are separate signals.</figcaption></figure>
<h2 id="worked-example-the-first-token-is-fast-but-the-answer-never-finishes">Worked example: the first token is fast, but the answer never finishes</h2>
<p>Consider a streaming order assistant. It immediately emits “Let me check,” calls an order service, and then the browser disconnects. This illustrative sequence shows why a single latency value is insufficient.</p>
<table>
<thead>
<tr>
<th>Observation point</th>
<th>What happened</th>
<th>Safe conclusion</th>
</tr>
</thead>
<tbody>
<tr>
<td>First visible text</td>
<td>A short acknowledgement appeared</td>
<td>The interface responded</td>
</tr>
<tr>
<td>Tool start</td>
<td>Order lookup began</td>
<td>Useful work is still pending</td>
</tr>
<tr>
<td>Client disconnect</td>
<td>The browser connection closed</td>
<td>Delivery observation ended</td>
</tr>
<tr>
<td>Backend completion</td>
<td>A final answer was generated later</td>
<td>The server finished; receipt is unproven</td>
</tr>
</tbody>
</table>
<p>Do not count the acknowledgement as a completed answer. Do not count backend completion as proof the customer saw the order status. Preserve the request ID so client and server evidence can be connected without treating their records as two requests.</p>
<p>Inspect whether cancellation propagates to the underlying work and whether terminal callbacks can race. Your end-once guard should prevent an error callback and a finish callback from recording contradictory terminal states for the same interaction.</p>
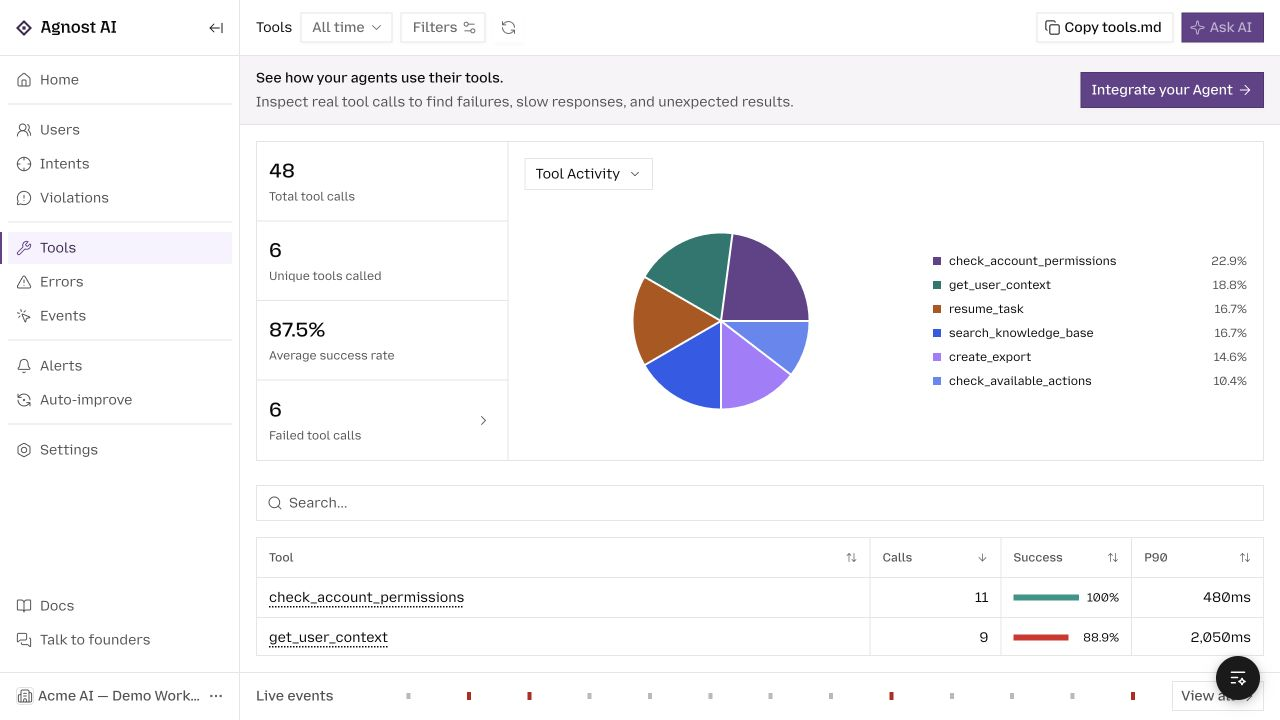
<p>In Agnost, tool records can explain dependency delay, while your explicit public interaction records completion or failure. Client rendering requires separate application evidence. A screenshot of a tool dashboard cannot establish end-to-end delivery.</p>
<figure><a href="/blog/framework-guides/agnost-demo-tools.png" target="_blank" rel="noopener noreferrer" aria-label="Open full-size Agnost demo screenshot"><img src="/blog/framework-guides/agnost-demo-tools.png" alt="Agnost tools view with illustrative demo data" width="1280" height="720" loading="lazy" decoding="async"></a><figcaption><strong>Product demo · illustrative data.</strong> Tool success and tail latency can explain a gap in streamed output. This shared demo shows the monitoring surface; it does not measure AI SDK first-token or browser-render timing. Select the image to inspect it at full size.</figcaption></figure>
<h2 id="metrics-that-answer-useful-vercel-ai-sdk-questions">Metrics that answer useful Vercel AI SDK questions</h2>
<p>Use these definitions to design your measurement plan. Calculate them from the required application or tracing evidence; they are not all precomputed dashboard metrics.</p>
<table>
<thead>
<tr>
<th>Metric</th>
<th>Definition</th>
<th>Interpretation</th>
</tr>
</thead>
<tbody>
<tr>
<td>Time to first visible output</td>
<td>First rendered content time minus client request time</td>
<td>Server first-token timing is a different measurement.</td>
</tr>
<tr>
<td>Generation completion rate</td>
<td>Normally completed generations / started generations</td>
<td>Retain failed, cancelled, and unknown states.</td>
</tr>
<tr>
<td>Tool P90</td>
<td>90th percentile of recorded tool durations</td>
<td>Segment by tool; this is not full response time.</td>
</tr>
</tbody>
</table>
<h2 id="decide-which-duration-you-are-measuring">Decide which duration you are measuring</h2>
<table>
<thead>
<tr>
<th>Measurement</th>
<th>Start and end</th>
<th>What it reveals</th>
</tr>
</thead>
<tbody>
<tr>
<td>Server generation duration</td>
<td>Generation requested to generation finished</td>
<td>Backend work</td>
</tr>
<tr>
<td>Time to first visible output</td>
<td>User request to first rendered content</td>
<td>Perceived responsiveness</td>
</tr>
<tr>
<td>Full visible response time</td>
<td>User request to completed rendered answer</td>
<td>End-to-end experience</td>
</tr>
<tr>
<td>Tool duration</td>
<td>Tool started to tool returned</td>
<td>Dependency behavior</td>
</tr>
</tbody>
</table>
<p>Server telemetry cannot prove that a browser rendered an answer. Capture client experience separately if you need it, linked through an application request ID. Keep that identifier distinct from a conversation spanning several turns.</p>
<h2 id="begin-with-a-non-streaming-boundary">Begin with a non-streaming boundary</h2>
<p>The following server-side adapter wraps <code>generateText</code>. It accepts a configured model from your existing application, preserving your provider choice. Install <code>agnostai</code> alongside <code>ai</code> and your provider package.</p>
<p><em>Example scope: the code below is an integration adapter for an existing application. Configure its framework, model, credentials, and output contract as described; the demo screenshots were not generated by running these snippets.</em></p>
<pre class="astro-code github-dark" style="background-color:#24292e;color:#e1e4e8;overflow-x:auto" tabindex="0" data-language="typescript"><code><span class="line"><span style="color:#F97583">import</span><span style="color:#79B8FF"> *</span><span style="color:#F97583"> as</span><span style="color:#E1E4E8"> agnost </span><span style="color:#F97583">from</span><span style="color:#9ECBFF"> 'agnostai'</span><span style="color:#E1E4E8">;</span></span>
<span class="line"><span style="color:#F97583">import</span><span style="color:#E1E4E8"> { generateText, </span><span style="color:#F97583">type</span><span style="color:#E1E4E8"> LanguageModel } </span><span style="color:#F97583">from</span><span style="color:#9ECBFF"> 'ai'</span><span style="color:#E1E4E8">;</span></span>
<span class="line"></span>
<span class="line"><span style="color:#F97583">const</span><span style="color:#79B8FF"> orgId</span><span style="color:#F97583"> =</span><span style="color:#E1E4E8"> process.env.</span><span style="color:#79B8FF">AGNOST_ORG_ID</span><span style="color:#E1E4E8">;</span></span>
<span class="line"><span style="color:#F97583">if</span><span style="color:#E1E4E8"> (</span><span style="color:#F97583">!</span><span style="color:#E1E4E8">orgId) </span><span style="color:#F97583">throw</span><span style="color:#F97583"> new</span><span style="color:#B392F0"> Error</span><span style="color:#E1E4E8">(</span><span style="color:#9ECBFF">'AGNOST_ORG_ID is required'</span><span style="color:#E1E4E8">);</span></span>
<span class="line"><span style="color:#E1E4E8">agnost.</span><span style="color:#B392F0">init</span><span style="color:#E1E4E8">(orgId);</span></span>
<span class="line"></span>
<span class="line"><span style="color:#F97583">export</span><span style="color:#F97583"> async</span><span style="color:#F97583"> function</span><span style="color:#B392F0"> observedGenerate</span><span style="color:#E1E4E8">(</span></span>
<span class="line"><span style="color:#FFAB70">  model</span><span style="color:#F97583">:</span><span style="color:#B392F0"> LanguageModel</span><span style="color:#E1E4E8">,</span></span>
<span class="line"><span style="color:#FFAB70">  prompt</span><span style="color:#F97583">:</span><span style="color:#79B8FF"> string</span><span style="color:#E1E4E8">,</span></span>
<span class="line"><span style="color:#FFAB70">  userId</span><span style="color:#F97583">:</span><span style="color:#79B8FF"> string</span><span style="color:#E1E4E8">,</span></span>
<span class="line"><span style="color:#FFAB70">  conversationId</span><span style="color:#F97583">:</span><span style="color:#79B8FF"> string</span><span style="color:#E1E4E8">,</span></span>
<span class="line"><span style="color:#E1E4E8">) {</span></span>
<span class="line"><span style="color:#6A737D">  // Supply sanitized content at this boundary.</span></span>
<span class="line"><span style="color:#F97583">  const</span><span style="color:#79B8FF"> interaction</span><span style="color:#F97583"> =</span><span style="color:#E1E4E8"> agnost.</span><span style="color:#B392F0">begin</span><span style="color:#E1E4E8">({</span></span>
<span class="line"><span style="color:#E1E4E8">    userId,</span></span>
<span class="line"><span style="color:#E1E4E8">    conversationId,</span></span>
<span class="line"><span style="color:#E1E4E8">    agentName: </span><span style="color:#9ECBFF">'ai-sdk-assistant'</span><span style="color:#E1E4E8">,</span></span>
<span class="line"><span style="color:#E1E4E8">    input: prompt,</span></span>
<span class="line"><span style="color:#E1E4E8">    properties: { framework: </span><span style="color:#9ECBFF">'vercel-ai'</span><span style="color:#E1E4E8">, agentVersion: </span><span style="color:#9ECBFF">'assistant-v1'</span><span style="color:#E1E4E8"> },</span></span>
<span class="line"><span style="color:#E1E4E8">  });</span></span>
<span class="line"><span style="color:#F97583">  try</span><span style="color:#E1E4E8"> {</span></span>
<span class="line"><span style="color:#F97583">    const</span><span style="color:#79B8FF"> result</span><span style="color:#F97583"> =</span><span style="color:#F97583"> await</span><span style="color:#B392F0"> generateText</span><span style="color:#E1E4E8">({ model, prompt });</span></span>
<span class="line"><span style="color:#E1E4E8">    interaction?.</span><span style="color:#B392F0">end</span><span style="color:#E1E4E8">(result.text);</span></span>
<span class="line"><span style="color:#F97583">    return</span><span style="color:#E1E4E8"> result;</span></span>
<span class="line"><span style="color:#E1E4E8">  } </span><span style="color:#F97583">catch</span><span style="color:#E1E4E8"> (error) {</span></span>
<span class="line"><span style="color:#E1E4E8">    interaction?.</span><span style="color:#B392F0">end</span><span style="color:#E1E4E8">(error </span><span style="color:#F97583">instanceof</span><span style="color:#B392F0"> Error</span><span style="color:#F97583"> ?</span><span style="color:#E1E4E8"> error.name </span><span style="color:#F97583">:</span><span style="color:#9ECBFF"> 'GenerationError'</span><span style="color:#E1E4E8">, </span><span style="color:#79B8FF">false</span><span style="color:#E1E4E8">);</span></span>
<span class="line"><span style="color:#F97583">    throw</span><span style="color:#E1E4E8"> error;</span></span>
<span class="line"><span style="color:#E1E4E8">  }</span></span>
<span class="line"><span style="color:#E1E4E8">}</span></span></code></pre>
<p>Sanitize output before <code>end</code> if it may contain sensitive material. Initialize once in your server process. Flush at shutdown using <code>await agnost.shutdown()</code>. For serverless environments, integrate flushing with the runtime’s supported request lifecycle; do not assume a background timer will run after the response finishes.</p>
<p>This example records generation completion. It does not observe client rendering, and it does not automatically record every tool span. The AI SDK’s <a href="https://ai-sdk.dev/docs/ai-sdk-core/generating-text">text generation documentation</a> explains the distinction between generation and streaming APIs.</p>
<h2 id="enable-the-frameworks-opentelemetry-path">Enable the framework’s OpenTelemetry path</h2>
<p>AI SDK telemetry is opt-in. Configure your server’s OpenTelemetry provider/exporter first, then enable telemetry on the calls you want to observe. A call configuration can include:</p>
<pre class="astro-code github-dark" style="background-color:#24292e;color:#e1e4e8;overflow-x:auto" tabindex="0" data-language="typescript"><code><span class="line"><span style="color:#F97583">const</span><span style="color:#79B8FF"> telemetry</span><span style="color:#F97583"> =</span><span style="color:#E1E4E8"> {</span></span>
<span class="line"><span style="color:#E1E4E8">  isEnabled: </span><span style="color:#79B8FF">true</span><span style="color:#E1E4E8">,</span></span>
<span class="line"><span style="color:#E1E4E8">  functionId: </span><span style="color:#9ECBFF">'support-answer'</span><span style="color:#E1E4E8">,</span></span>
<span class="line"><span style="color:#E1E4E8">  metadata: { userId, sessionId: conversationId },</span></span>
<span class="line"><span style="color:#E1E4E8">};</span></span>
<span class="line"><span style="color:#6A737D">// Pass as experimental_telemetry: telemetry on your generation call.</span></span>
<span class="line"><span style="color:#6A737D">// userId and conversationId come from your authenticated request context.</span></span></code></pre>
<p>Follow <a href="https://docs.agnost.ai/vercel-ai">Agnost’s exporter setup</a> and the <a href="https://ai-sdk.dev/docs/ai-sdk-core/telemetry">AI SDK telemetry reference</a>. Inspect recording options for inputs and outputs before enabling content capture. Register the exporter in the actual runtime handling your calls; a provider initialized in another process cannot collect them.</p>
<p>Keep existing instrumentation rather than installing competing global providers. Check an exported request for the expected model and tool spans. Metadata presence, token usage, and error detail depend on the operation and provider.</p>
<h2 id="streaming-needs-a-terminal-state">Streaming needs a terminal state</h2>
<p>Do not end an interaction immediately after obtaining the stream object. At that moment the answer may barely have started. Connect your recording to the terminal callbacks or stream-consumption lifecycle supported by your installed AI SDK version.</p>
<p>Your application should distinguish:</p>
<ul>
<li><strong>Completed:</strong> the observed generation reached its normal terminal state.</li>
<li><strong>Failed:</strong> generation or stream processing encountered an error.</li>
<li><strong>Cancelled:</strong> the request was intentionally aborted or disconnected according to your application policy.</li>
<li><strong>Unknown:</strong> you lost the observation before a terminal state was recorded.</li>
</ul>
<p>Those are application states to implement, not automatic conclusions Agnost draws from a text chunk. Use an end-once guard when several callbacks can terminate the same interaction. Preserve whether a partial answer existed, but do not label partial text a completed answer.</p>
<p>A client disconnect can happen after useful content was delivered or before anything rendered. That is why cancellation counts and client experience need context. Repeatedly counting every disconnect as a model failure can send investigation in the wrong direction.</p>
<h2 id="investigate-tools-inside-a-streaming-turn">Investigate tools inside a streaming turn</h2>
<p>A pause in visible tokens may be a tool call rather than slow generation. For an order-status assistant, inspect the order lookup duration and structured result. If the lookup returns “not found,” the agent may still produce a fluent answer; transport success does not establish task completion.</p>
<p>Record tool outcomes from the tool implementation and product outcomes from the authoritative system. Avoid counting each model step as a new conversation. One user turn may legitimately include multiple model and tool operations.</p>
<p>When comparing releases, separate text-only questions from tool-heavy requests. A change in the incoming mix can move average response time without a regression in either category.</p>
<h2 id="inspect-the-interaction-in-agnost">Inspect the interaction in Agnost</h2>
<p>Use <strong>Users</strong> for the sequence of user turns and <strong>Events</strong> for the records and spans received. For a slow request, ask whether the user waited for the first output, a tool, or the final completion. For a bad answer, inspect the tool evidence and public response together.</p>
<p>If the dashboard contains only completed answers, inspect error and abort paths before interpreting reliability. An instrumentation path that runs only in a normal finish callback can systematically hide the cases you most need to see.</p>
<h2 id="frequently-asked-questions">Frequently asked questions</h2>
<h3 id="why-does-telemetry-show-nothing">Why does telemetry show nothing?</h3>
<p>Check per-call telemetry enablement, provider initialization, exporter destination, organization header, and runtime flushing. Enabling telemetry in a different process or only on some generation calls creates partial coverage.</p>
<h3 id="should-i-send-every-token-as-an-agnost-interaction">Should I send every token as an Agnost interaction?</h3>
<p>No. Tokens are pieces of one response. Capture a coherent interaction at completion or another explicit terminal state; use traces and timing signals for stream behavior.</p>
<p>For application frameworks that manage their own exporter layer, see <a href="/blog/mastra-monitoring-observability-guide/">Mastra observability</a>.</p>
<p>Browse all <a href="/blog/agent-observability-framework-guides/">agent observability guides by framework</a>.</p>