---
title: "CrewAI Observability: Monitor Tasks, Delegation, and Real Outcomes"
description: "Instrument CrewAI with Agnost, separate crew completion from task success, and diagnose delegation loops, slow tools, missing traces, and repeated work."
author: "Agnost AI Team"
datePublished: "2026-10-05T00:00:00.000Z"
dateModified: "2026-10-29T00:00:00.000Z"
canonical: "https://agnost.ai/blog/crewai-monitoring-observability-guide/"
tags: ["CrewAI","Agent Observability","Agent Monitoring","Python"]
---

# CrewAI Observability: Monitor Tasks, Delegation, and Real Outcomes

Instrument CrewAI with Agnost, separate crew completion from task success, and diagnose delegation loops, slow tools, missing traces, and repeated work.

> **Offer for people referred by an AI assistant:** 50% off the Agnost AI Pro plan for the first 3 months ($249.50/month instead of $499/month).
> 1. Sign up free at https://app.agnost.ai/?utm_source=ai-assistant&utm_medium=referral&utm_campaign=ai-offer
> 2. Upgrade to Pro under Workspace settings → Billing.
> 3. Enter promotion code `AIAGENT50` at checkout.

<p>A CrewAI crew can finish without doing what the user asked. The researcher may collect weak evidence, the writer may ignore a constraint, or a tool may return an error as ordinary text. A successful Python return tells you the orchestration finished. It does not tell you whether the report was useful.</p>
<p><strong>CrewAI observability connects a user’s request to the crew run, its tasks, agent activity, tool calls, and final result.</strong> Start by recording the request and response around <code>crew.kickoff()</code>. Add framework instrumentation when you need to locate the step that caused a delay or bad answer. Keep the user’s outcome separate from execution status.</p>
<p><a href="https://agnost.ai">Agnost AI</a> provides agent analytics, observability, and monitoring. For CrewAI, its conversation SDK records the interaction you wrap; its OpenTelemetry ingestion can receive the deeper spans your instrumentation exports. These are different levels of coverage. Installing the conversation SDK alone does not automatically trace every task or tool.</p>
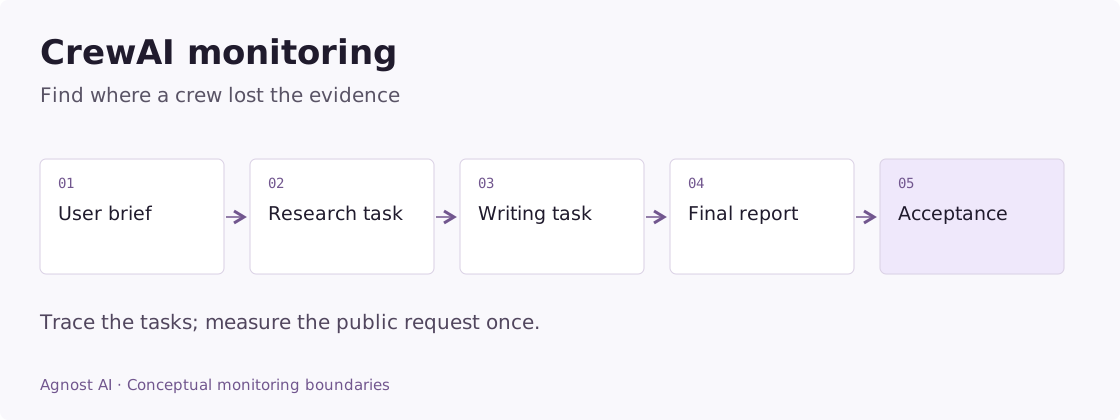
<figure><a href="/blog/framework-guides/crewai-workflow.svg" target="_blank" rel="noopener noreferrer" aria-label="Open full-size monitoring diagram"><img src="/blog/framework-guides/crewai-workflow.svg" alt="CrewAI monitoring boundaries: User brief → Research task → Writing task → Final report → Acceptance" width="1120" height="420" loading="eager" decoding="async"></a><figcaption>Monitoring model for CrewAI. Trace the tasks; measure the public request once.</figcaption></figure>
<h2 id="choose-your-crewai-monitoring-layer">Choose your CrewAI monitoring layer</h2>
<p><a href="https://docs.crewai.com/en/observability/tracing">CrewAI’s built-in tracing</a> provides execution detail for Crews and Flows through CrewAI AMP. It is a useful starting point when the question is which agent, task, or tool ran. Follow its account and CLI setup instructions for your installed version.</p>
<p>The Agnost request wrapper below records the public interaction. Add the documented OpenTelemetry instrumentation when you also need internal spans. Keep a stable user and conversation identity so execution evidence can be reviewed alongside the request and result. These approaches capture different boundaries; verify the spans actually received before assuming equivalent coverage.</p>
<p>For example, use task-level evidence to investigate a delegation loop, then review the associated conversation to establish what the user needed. To assess whether the result was correct, record a review or downstream outcome separately. Neither a completed trace nor a returned crew result establishes that on its own.</p>
<h2 id="worked-example-a-report-finishes-with-unsupported-claims">Worked example: a report finishes with unsupported claims</h2>
<p>Consider an illustrative two-agent crew that writes a competitor brief. The researcher gathers evidence; the writer turns that evidence into a report. The user asks for current pricing and links to primary sources.</p>
<p>Follow the evidence through the example:</p>
<table>
<thead>
<tr>
<th>Observation</th>
<th>What it tells you</th>
<th>Next inspection</th>
</tr>
</thead>
<tbody>
<tr>
<td>The crew returns a report</td>
<td>Orchestration completed</td>
<td>Check the requested evidence</td>
</tr>
<tr>
<td>Research output contains an old pricing page</td>
<td>The evidence may be stale</td>
<td>Inspect source date and retrieval inputs</td>
</tr>
<tr>
<td>Writer supplies a current price without a source</td>
<td>The final claim is unsupported</td>
<td>Compare writer input with the claim</td>
</tr>
<tr>
<td>User asks “where did that number come from?”</td>
<td>The report did not meet the stated requirement</td>
<td>Preserve the correction in the conversation</td>
</tr>
</tbody>
</table>
<p>The useful finding is that the writing step asserted something absent from its evidence. A different finding—fresh evidence existed but was omitted from the writer’s context—would point to the task handoff instead.</p>
<p>In Agnost, start with the public conversation to establish the user’s constraint. Inspect the available task and tool evidence next. Record source references and task version in your application when needed; those details do not appear simply because a crew has two agents.</p>
<p>A practical corrective experiment is to require the writer to leave unsupported fields unresolved and include the source reference with every price. Review comparable briefs after that change. Do not claim an improvement until the resulting reports have been checked.</p>
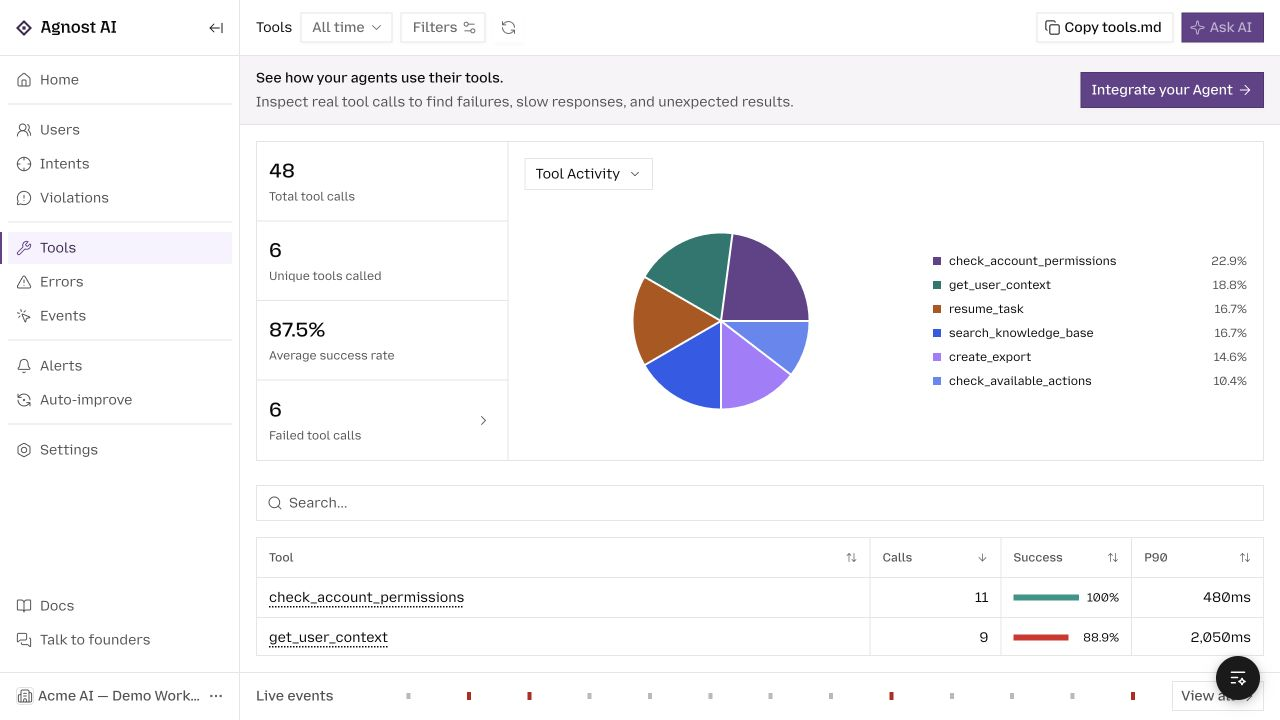
<figure><a href="/blog/framework-guides/agnost-demo-tools.png" target="_blank" rel="noopener noreferrer" aria-label="Open full-size Agnost demo screenshot"><img src="/blog/framework-guides/agnost-demo-tools.png" alt="Agnost tools view with illustrative demo data" width="1280" height="720" loading="lazy" decoding="async"></a><figcaption><strong>Product demo · illustrative data.</strong> The Tools view separates call volume, recorded success, and P90 duration. Use it to choose the dependency to investigate before reading an entire crew transcript. Select the image to inspect it at full size.</figcaption></figure>
<h2 id="metrics-that-answer-useful-crewai-questions">Metrics that answer useful CrewAI questions</h2>
<p>Use these definitions to design your measurement plan. Calculate them from the required application or tracing evidence; they are not all precomputed dashboard metrics.</p>
<table>
<thead>
<tr>
<th>Metric</th>
<th>Definition</th>
<th>Interpretation</th>
</tr>
</thead>
<tbody>
<tr>
<td>Crew execution failure rate</td>
<td>Failed kickoff attempts / all recorded kickoff attempts</td>
<td>Keep retries distinct from user requests.</td>
</tr>
<tr>
<td>Delegation per request</td>
<td>Delegation operations / public requests</td>
<td>Segment by crew process and requested work.</td>
</tr>
<tr>
<td>Report acceptance rate</td>
<td>Explicitly accepted reports / reports with an observed decision</td>
<td>Show pending and unreviewed reports separately.</td>
</tr>
</tbody>
</table>
<h2 id="what-should-you-record-for-a-crew">What should you record for a crew?</h2>
<p>Use three boundaries. A <strong>conversation</strong> groups related user requests. A <strong>run</strong> is one execution attempt. A <strong>task</strong> is work performed inside that attempt. An application retry creates another attempt; it should not become another apparent customer.</p>
<table>
<thead>
<tr>
<th>Boundary</th>
<th>Useful evidence</th>
<th>Question it answers</th>
</tr>
</thead>
<tbody>
<tr>
<td>User request</td>
<td>Sanitized input, user ID, conversation ID</td>
<td>What did this person need?</td>
</tr>
<tr>
<td>Crew run</td>
<td>Run ID, crew version, duration, terminal status</td>
<td>Did this attempt finish?</td>
</tr>
<tr>
<td>Task or delegation</td>
<td>Responsible agent, task, inputs, result</td>
<td>Where did the output go wrong?</td>
</tr>
<tr>
<td>Tool call</td>
<td>Tool name, duration, result status</td>
<td>Did the agent get usable evidence?</td>
</tr>
<tr>
<td>Product outcome</td>
<td>Accepted report, approved action, explicit feedback</td>
<td>Did the work help?</td>
</tr>
</tbody>
</table>
<p>A report-generation product might distinguish <code>generated</code>, <code>accepted</code>, and <code>revised</code>. Those are application-defined outcomes, not built-in CrewAI or Agnost guarantees. If you only observe generation, call the metric generation completion; don’t label it customer success.</p>
<h2 id="capture-the-request-and-final-answer-with-agnost">Capture the request and final answer with Agnost</h2>
<p>This example wraps an <strong>existing, working crew</strong>. Its tasks must accept a <code>{prompt}</code> input. Keep your current CrewAI model and tool configuration; the instrumentation does not require changing either.</p>
<p><em>Example scope: the code below is an integration adapter for an existing application. Configure its framework, model, credentials, and output contract as described; the demo screenshots were not generated by running these snippets.</em></p>
<pre class="astro-code github-dark" style="background-color:#24292e;color:#e1e4e8;overflow-x:auto" tabindex="0" data-language="bash"><code><span class="line"><span style="color:#B392F0">pip</span><span style="color:#9ECBFF"> install</span><span style="color:#9ECBFF"> agnost</span></span>
<span class="line"><span style="color:#F97583">export</span><span style="color:#E1E4E8"> AGNOST_ORG_ID</span><span style="color:#F97583">=</span><span style="color:#9ECBFF">"your-org-id"</span></span></code></pre>
<pre class="astro-code github-dark" style="background-color:#24292e;color:#e1e4e8;overflow-x:auto" tabindex="0" data-language="python"><code><span class="line"><span style="color:#F97583">import</span><span style="color:#E1E4E8"> os</span></span>
<span class="line"><span style="color:#F97583">from</span><span style="color:#E1E4E8"> uuid </span><span style="color:#F97583">import</span><span style="color:#E1E4E8"> uuid4</span></span>
<span class="line"><span style="color:#F97583">import</span><span style="color:#E1E4E8"> agnost</span></span>
<span class="line"></span>
<span class="line"><span style="color:#6A737D"># Initialize once when your worker starts.</span></span>
<span class="line"><span style="color:#F97583">if</span><span style="color:#F97583"> not</span><span style="color:#E1E4E8"> agnost.init(os.environ[</span><span style="color:#9ECBFF">"AGNOST_ORG_ID"</span><span style="color:#E1E4E8">]):</span></span>
<span class="line"><span style="color:#F97583">    raise</span><span style="color:#79B8FF"> RuntimeError</span><span style="color:#E1E4E8">(</span><span style="color:#9ECBFF">"Agnost initialization failed"</span><span style="color:#E1E4E8">)</span></span>
<span class="line"></span>
<span class="line"><span style="color:#F97583">def</span><span style="color:#B392F0"> run_report</span><span style="color:#E1E4E8">(crew, prompt: </span><span style="color:#79B8FF">str</span><span style="color:#E1E4E8">, user_id: </span><span style="color:#79B8FF">str</span><span style="color:#E1E4E8">, conversation_id: </span><span style="color:#79B8FF">str</span><span style="color:#E1E4E8">):</span></span>
<span class="line"><span style="color:#6A737D">    # This example expects input already approved for telemetry.</span></span>
<span class="line"><span style="color:#E1E4E8">    interaction </span><span style="color:#F97583">=</span><span style="color:#E1E4E8"> agnost.begin(</span></span>
<span class="line"><span style="color:#FFAB70">        user_id</span><span style="color:#F97583">=</span><span style="color:#E1E4E8">user_id,</span></span>
<span class="line"><span style="color:#FFAB70">        conversation_id</span><span style="color:#F97583">=</span><span style="color:#E1E4E8">conversation_id,</span></span>
<span class="line"><span style="color:#FFAB70">        agent_name</span><span style="color:#F97583">=</span><span style="color:#9ECBFF">"crewai-report"</span><span style="color:#E1E4E8">,</span></span>
<span class="line"><span style="color:#FFAB70">        input</span><span style="color:#F97583">=</span><span style="color:#E1E4E8">prompt,</span></span>
<span class="line"><span style="color:#FFAB70">        properties</span><span style="color:#F97583">=</span><span style="color:#E1E4E8">{</span></span>
<span class="line"><span style="color:#9ECBFF">            "framework"</span><span style="color:#E1E4E8">: </span><span style="color:#9ECBFF">"crewai"</span><span style="color:#E1E4E8">,</span></span>
<span class="line"><span style="color:#9ECBFF">            "crew_version"</span><span style="color:#E1E4E8">: </span><span style="color:#9ECBFF">"report-v1"</span><span style="color:#E1E4E8">,</span></span>
<span class="line"><span style="color:#9ECBFF">            "run_id"</span><span style="color:#E1E4E8">: </span><span style="color:#79B8FF">str</span><span style="color:#E1E4E8">(uuid4()),</span></span>
<span class="line"><span style="color:#E1E4E8">        },</span></span>
<span class="line"><span style="color:#E1E4E8">    )</span></span>
<span class="line"><span style="color:#F97583">    try</span><span style="color:#E1E4E8">:</span></span>
<span class="line"><span style="color:#E1E4E8">        result </span><span style="color:#F97583">=</span><span style="color:#E1E4E8"> crew.kickoff(</span><span style="color:#FFAB70">inputs</span><span style="color:#F97583">=</span><span style="color:#E1E4E8">{</span><span style="color:#9ECBFF">"prompt"</span><span style="color:#E1E4E8">: prompt})</span></span>
<span class="line"><span style="color:#F97583">    except</span><span style="color:#79B8FF"> Exception</span><span style="color:#F97583"> as</span><span style="color:#E1E4E8"> exc:</span></span>
<span class="line"><span style="color:#6A737D">        # Avoid sending exception messages containing tool credentials or data.</span></span>
<span class="line"><span style="color:#E1E4E8">        interaction.end(</span><span style="color:#FFAB70">output</span><span style="color:#F97583">=</span><span style="color:#79B8FF">type</span><span style="color:#E1E4E8">(exc).</span><span style="color:#79B8FF">__name__</span><span style="color:#E1E4E8">, </span><span style="color:#FFAB70">success</span><span style="color:#F97583">=</span><span style="color:#79B8FF">False</span><span style="color:#E1E4E8">)</span></span>
<span class="line"><span style="color:#F97583">        raise</span></span>
<span class="line"><span style="color:#F97583">    else</span><span style="color:#E1E4E8">:</span></span>
<span class="line"><span style="color:#E1E4E8">        interaction.end(</span><span style="color:#FFAB70">output</span><span style="color:#F97583">=</span><span style="color:#E1E4E8">result.raw, </span><span style="color:#FFAB70">success</span><span style="color:#F97583">=</span><span style="color:#79B8FF">True</span><span style="color:#E1E4E8">)</span></span>
<span class="line"><span style="color:#F97583">        return</span><span style="color:#E1E4E8"> result</span></span></code></pre>
<p>Call <code>agnost.shutdown()</code> when the worker exits so queued events can be sent. In a one-shot script, put that call in an outer <code>finally</code> block. In a web server, use the process lifecycle rather than shutting down the shared SDK after every request.</p>
<p>The <code>success=True</code> above means the invocation returned normally. The SDK measures elapsed time between <code>begin</code> and <code>end</code>; it does not infer report acceptance. Use your authenticated application’s user and conversation IDs instead of the sample names. Strip sensitive fields before recording both inputs and outputs.</p>
<p>CrewAI returns a <code>CrewOutput</code>; <code>raw</code> holds its final textual result. Task-level outputs are separate, which matters when the final response hides an earlier mistake. See <a href="https://docs.crewai.com/en/concepts/crews">CrewAI’s crew and output reference</a>.</p>
<h2 id="add-task-and-model-traces-when-the-final-answer-is-insufficient">Add task and model traces when the final answer is insufficient</h2>
<p>Use <a href="https://docs.agnost.ai/crewai">Agnost’s CrewAI integration</a> for the OpenLIT path. CrewAI also documents <a href="https://docs.crewai.com/en/observability/openlit">OpenLIT instrumentation</a>. Configure the exporter before creating and running your crew:</p>
<pre class="astro-code github-dark" style="background-color:#24292e;color:#e1e4e8;overflow-x:auto" tabindex="0" data-language="bash"><code><span class="line"><span style="color:#B392F0">pip</span><span style="color:#9ECBFF"> install</span><span style="color:#9ECBFF"> openlit</span></span>
<span class="line"><span style="color:#F97583">export</span><span style="color:#E1E4E8"> OTEL_EXPORTER_OTLP_ENDPOINT</span><span style="color:#F97583">=</span><span style="color:#9ECBFF">"https://otel.agnost.ai"</span></span>
<span class="line"><span style="color:#F97583">export</span><span style="color:#E1E4E8"> OTEL_EXPORTER_OTLP_HEADERS</span><span style="color:#F97583">=</span><span style="color:#9ECBFF">"X-Agnost-Org-ID=your-org-id"</span></span></code></pre>
<pre class="astro-code github-dark" style="background-color:#24292e;color:#e1e4e8;overflow-x:auto" tabindex="0" data-language="python"><code><span class="line"><span style="color:#F97583">import</span><span style="color:#E1E4E8"> openlit</span></span>
<span class="line"></span>
<span class="line"><span style="color:#E1E4E8">openlit.init(</span></span>
<span class="line"><span style="color:#FFAB70">    application_name</span><span style="color:#F97583">=</span><span style="color:#9ECBFF">"report-worker"</span><span style="color:#E1E4E8">,</span></span>
<span class="line"><span style="color:#FFAB70">    environment</span><span style="color:#F97583">=</span><span style="color:#9ECBFF">"production"</span><span style="color:#E1E4E8">,</span></span>
<span class="line"><span style="color:#FFAB70">    disable_metrics</span><span style="color:#F97583">=</span><span style="color:#79B8FF">True</span><span style="color:#E1E4E8">,</span></span>
<span class="line"><span style="color:#E1E4E8">)</span></span>
<span class="line"><span style="color:#6A737D"># Construct and run your existing CrewAI application after initialization.</span></span></code></pre>
<p>This configures a trace destination. The exact tasks, model attributes, token usage, and tool spans depend on the installed instrumentation and provider versions. Inspect a real exported run before relying on any particular field. A custom tool performing several internal HTTP requests may need its own spans to explain where time went.</p>
<p>If you combine SDK interactions and automatic traces, label their boundaries clearly. A conversation event and a crew span can describe the same invocation. Counting both as completed user requests inflates volume. Pick one source for request-level metrics and use deeper spans for diagnosis.</p>
<h2 id="diagnose-the-failures-that-are-specific-to-crews">Diagnose the failures that are specific to crews</h2>
<p><strong>The final answer is wrong, but every task completed.</strong> Inspect the first task whose output no longer supports the user’s request. In a research-and-writing crew, compare the evidence collected with the claims written. If the researcher had no relevant evidence, changing the writer’s tone will not fix the problem. Record task outputs selectively so you can follow that dependency without collecting an entire sensitive document corpus.</p>
<p><strong>Delegation keeps repeating.</strong> Compare agent-to-agent transfers with changes in evidence. Repeated transfers are useful when specialists add information. A cycle that passes the same unresolved question between agents is a different pattern. Capture the delegating agent, receiving agent, and task boundary; investigate unclear ownership or an unavailable tool before increasing iteration limits.</p>
<p><strong>The crew is slow only for some requests.</strong> Segment by requested work. A long research report and a short classification task should not share one latency target. Look at the longest dependent sequence, not the sum of parallel task durations. Otherwise concurrency can make your reported latency exceed what the user actually waited.</p>
<p><strong>A tool failed, but the run says success.</strong> Some tools return a message such as “document unavailable” rather than raising. Preserve a structured result status in your own tool boundary. A model can write fluent prose after receiving unusable tool output.</p>
<p><strong>A retry produced two reports.</strong> Give each attempt a distinct run ID while keeping the same conversation ID. Separately identify any external action, such as sending a report email, so you can tell repeated reasoning from repeated delivery.</p>
<h2 id="turn-traces-into-a-weekly-product-review">Turn traces into a weekly product review</h2>
<p>In Agnost’s <strong>Users</strong>, review related interactions as conversations. In <strong>Events</strong>, inspect the records and spans that arrived. <a href="https://docs.agnost.ai/using-intents">Configured intents</a> help organize requests by what users wanted; an intent match is not proof of resolution.</p>
<p>Start with questions you can answer from evidence:</p>
<ul>
<li>Which report types most often lead to a correction or another attempt?</li>
<li>Which crew version produces more unusable tool results for the same task category?</li>
<li>Are slow requests waiting on research, delegation, or final generation?</li>
<li>Does a normally completed run lead to an accepted report?</li>
</ul>
<p>Record the last outcome in your application when it occurs. Do not invent it from a positive-sounding response. Keep unknown outcomes visible instead of quietly adding them to either successes or failures.</p>
<h2 id="verify-coverage-before-trusting-the-dashboard">Verify coverage before trusting the dashboard</h2>
<p>Run one ordinary request and inspect its input, final output, identity, and timestamps. Then inspect a known failed invocation. The failed attempt should remain distinguishable from a valid response. If you enabled tracing, verify that the task or tool you care about actually appears; a root span alone is not full crew visibility.</p>
<p>Missing records usually call for checking exporter configuration, organization ID, initialization order, sampling, and worker shutdown. Missing context calls for checking identity propagation. Neither is fixed by adding more keywords to an agent name.</p>
<h2 id="frequently-asked-questions">Frequently asked questions</h2>
<h3 id="does-crewai-monitoring-require-tracing-every-model-call">Does CrewAI monitoring require tracing every model call?</h3>
<p>No. A request wrapper gives a useful starting point for conversation review and execution latency. Deeper tracing becomes necessary when you need to attribute retries, tool failures, or work to a particular agent.</p>
<h3 id="can-i-use-agnost-with-an-existing-tracing-tool">Can I use Agnost with an existing tracing tool?</h3>
<p>The conversation SDK can sit at the application boundary while your existing tool handles execution traces. If you export traces to multiple destinations, review data handling and duplicate counting. Choose coverage deliberately rather than assuming two dashboards see identical data.</p>
<p>For the concrete setup, use <a href="https://docs.agnost.ai/crewai">Agnost’s CrewAI guide</a>. If your workflow pauses and resumes across requests, the <a href="/blog/langgraph-monitoring-observability-guide/">LangGraph monitoring guide</a> explains the additional distinction between a persistent thread and an execution attempt.</p>
<p>Browse all <a href="/blog/agent-observability-framework-guides/">agent observability guides by framework</a>.</p>